
Machine Learning Studio
6.3K
구독자
27
영상
최근 영상

Encoder-Decoder Architecture in Transformers

Parameter Efficient Fine Tuning PEFT
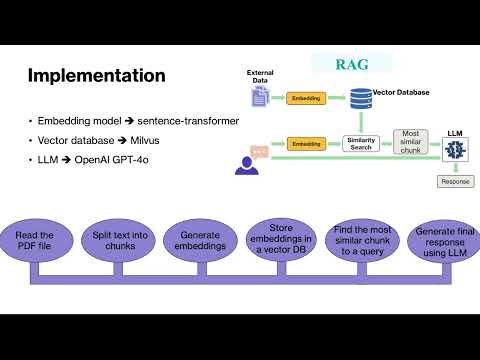
Retrieval Augmented Generation (RAG)

Enhancing LLMs (an overview)

FlashAttention: Accelerate LLM training

An Overview of Object Recognition Tasks

Dataset Management with FiftyOne

OpenAI CLIP model explained

DINO -- Self-supervised ViT

Swin Transformer

Variants of ViT: DeiT and T2T-ViT

Vision Transformer (ViT)

Evolution of Self-Attention in Vision
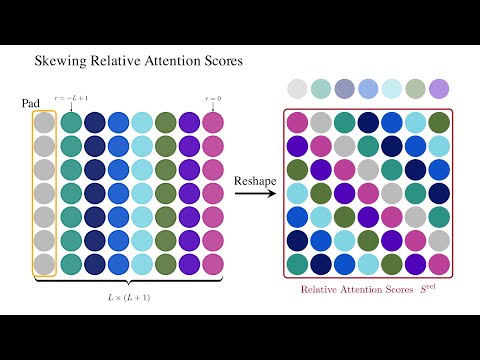
Relative Self-Attention Explained

Self-Attention in Image Domain: Non-Local Module

Introducing a new series on Vision Transformers
Linear Complexity in Attention Mechanism: A step-by-step implementation in PyTorch

Efficient Self-Attention for Transformers

Variants of Multi-head attention: Multi-query (MQA) and Grouped-query attention (GQA)

PostLN, PreLN and ResiDual Transformers

Transformer Architecture

Top Optimizers for Neural Networks

A Dive Into Multihead Attention, Self-Attention and Cross-Attention

Self-Attention Using Scaled Dot-Product Approach

GPT-4 release: a 5-minute overview

Matrix Multiplication Concept Explained

A Review of 10 Most Popular Activation Functions in Neural Networks